Document intelligence and review
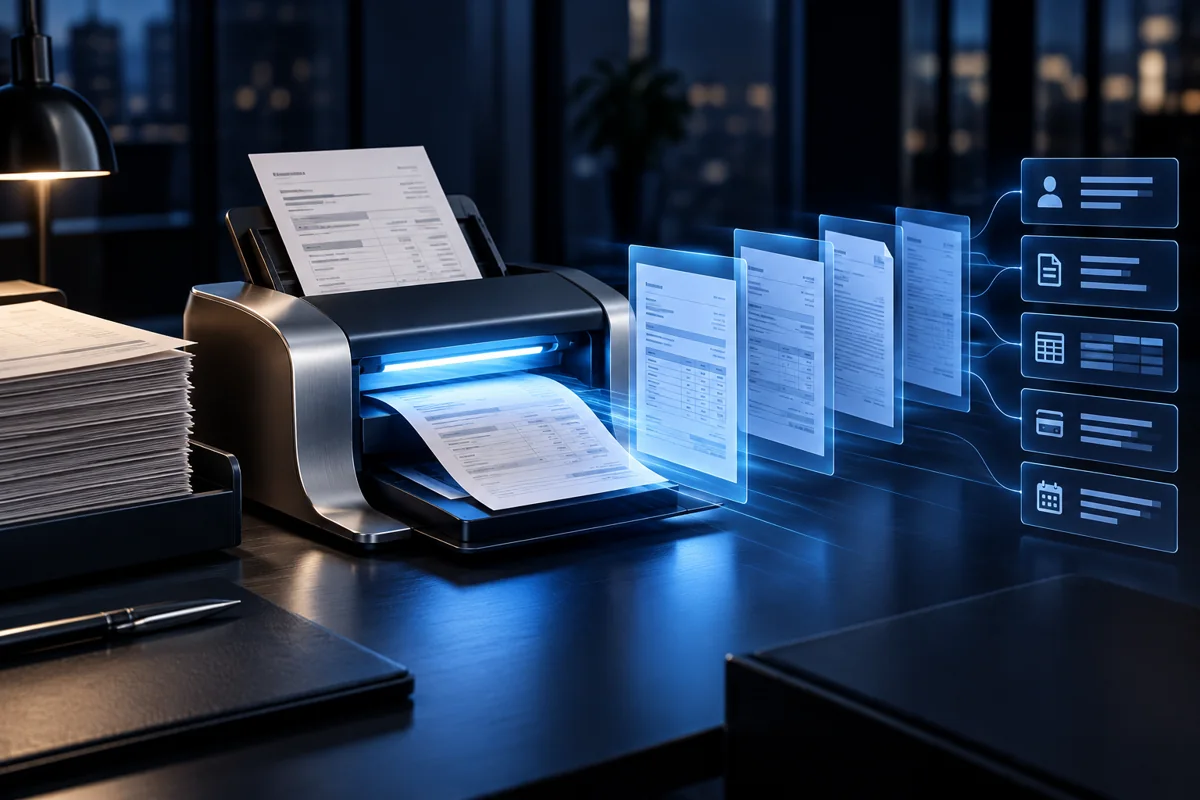
Extract and classify business information while keeping exceptions and review decisions traceable.
The situation.
A team processes documents with varied layouts and incomplete information. The workflow needs to distinguish extracted content from validated facts and route uncertainty to the right reviewer before downstream action.
A practical approach.
- 01
Define the information
Specify document types, fields, classifications and the consequences of each error.
- 02
Design the workflow
Connect ingestion, extraction, validation and human review with a traceable source reference.
- 03
Evaluate variation
Test representative layouts, scans, missing fields and ambiguous examples before expanding volume.
What to validate
- Do not treat a model confidence value as proof that a field is correct.
- Define exception ownership and approval before consequential downstream actions.
Typical outputs
- Document and field specification
- Processing and review architecture
- Error analysis and acceptance dataset
Example measures
- Field accuracy on held-out documents
- Exceptions requiring review
- Processing time including correction
Agree a baseline and acceptance criteria for the specific project.
Illustrative scenario and conceptual imagery. Scope, deliverables and acceptance evidence are agreed for each engagement; example measures are not achieved results.